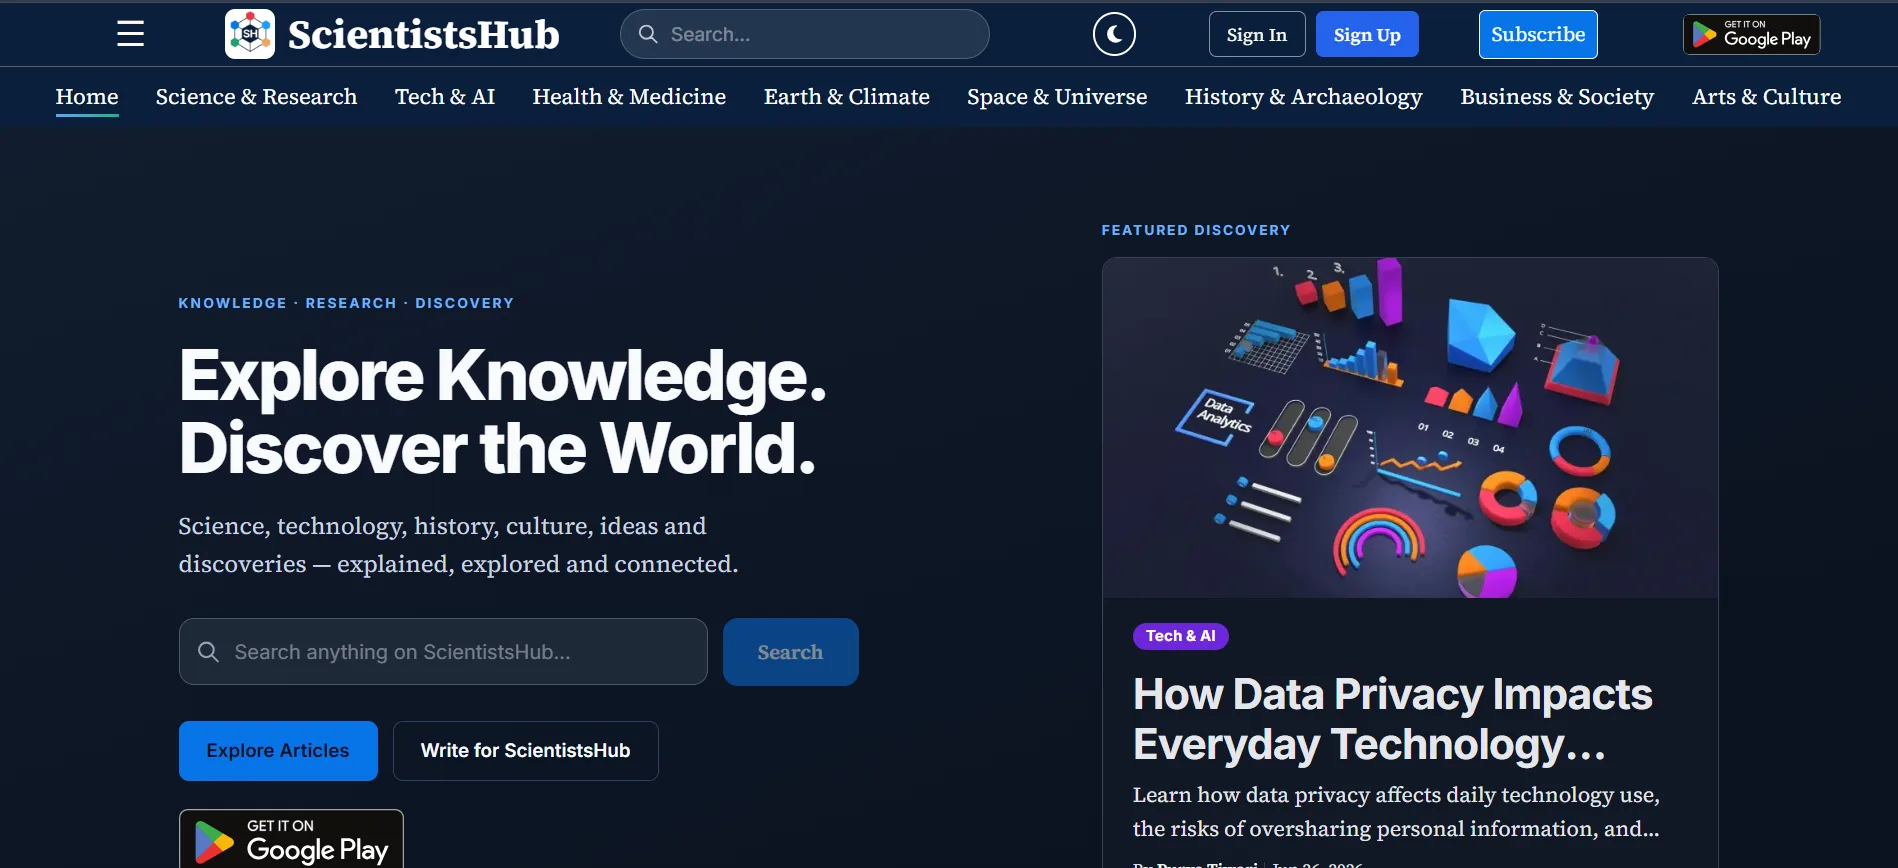
ScientistsHub — Making Peer-Reviewed Science Readable
A Next.js publishing platform for science communication, built to stay fast and stay up when the research APIs it depends on do not.
- Role
- Full-stack developer — architecture, API layer, editor, deployment
- Timeline
- Ongoing
- Team
- Solo build, client-directed
- Client
- ScientistsHub
- Stack
- Next.js 15 · React 19 · TypeScript 5.9 · TipTap Editor · MDX · CSS Modules · PWA · Vercel Analytics
Overview
ScientistsHub publishes science writing for a general audience — work that is accurate enough to survive scrutiny from researchers, but readable by people without a background in the field.
The platform spans four scientific categories and currently carries more than eighteen long-form articles, served from a Next.js 15 App Router application with server-side rendering and progressive-web-app support.
The Challenge
Two problems shaped the build, and they pulled in opposite directions.
The editorial workflow needed rich, structured articles — figures, citations, embedded formatting — without handing writers raw Markdown or raw HTML.
The platform depends on external research APIs that are rate limited and not always available. A slow or failing upstream could not be allowed to take the site down with it.
A conventional fetch-on-render approach would have satisfied the first and failed the second.
Architecture
The application is built on the Next.js App Router with server-side rendering, organised around a component-driven TypeScript architecture and served as an installable PWA with offline support.
The API layer is where most of the design effort went:
A dual-mode API system that serves live upstream data when it is healthy and falls back gracefully when it is not.
Circuit breaker patterns, so a failing upstream is bypassed rather than retried into the ground.
Rate limiting with exponential backoff, tuned to the 60 requests-per-minute ceiling the upstream imposes.
In-memory caching with a 15-minute TTL, which absorbs the majority of repeat reads.
The effect is that upstream degradation shows up as slightly staler content rather than as an error page.
The Solution
Editorially, the platform runs on TipTap with MDX support, giving writers a structured editor that produces validated documents rather than free-form markup. Articles support full CRUD, and images are optimised and lazy-loaded on the way out.
Discovery is handled by a dynamic sitemap covering the article set and JSON-LD structured data on every page, so published work is indexable the moment it goes live.
Results
The production build scores 99 on Lighthouse and loads in under 0.8 seconds, across more than forty dynamically routed pages.
The more useful outcome is less measurable: upstream rate limits and outages, which previously surfaced to readers as failures, are now absorbed by the caching and circuit-breaker layer and are invisible from the front end.
Key Learnings
Treating an unreliable upstream as a normal operating condition rather than an error case changes the architecture substantially — and is much harder to retrofit than to design in.
A constrained rich-text editor is worth the setup cost. Validating documents at the boundary means the renderer never has to defend itself against whatever the editor produced.
Caching decisions are content decisions. A 15-minute TTL is a judgement about how stale this particular material is allowed to be, not a purely technical setting.